
What Is RAG?
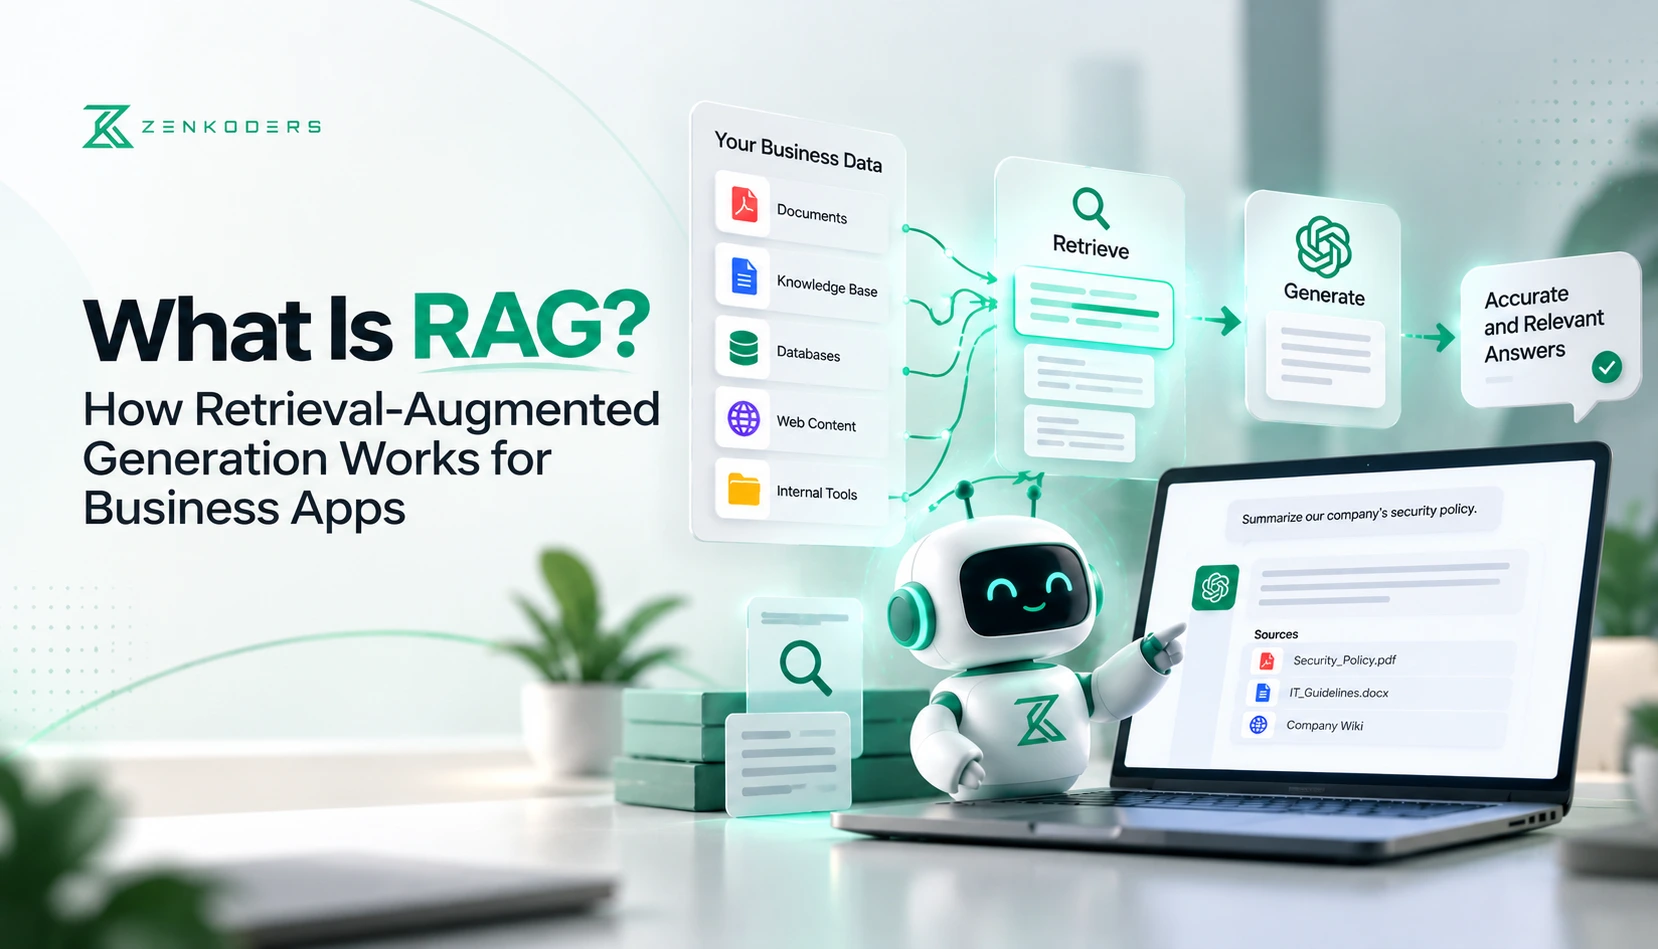
Retrieval-augmented generation (RAG) is an AI architecture that lets a large language model (LLM) look up relevant information from your own documents, databases, or APIs before it answers. Instead of relying only on what it learned in training, the model reads retrieved passages first, so its answers are current, specific to your business, and traceable to a source.
If you have ever asked a general chatbot about your refund policy or last quarter’s pricing and received a confident wrong answer, you have seen the problem RAG solves. A model’s training data is frozen, mostly public, and silent about your internal knowledge. RAG connects the model to that knowledge at the moment a question is asked, with no retraining.
This guide is written for founders, CTOs, and product owners deciding whether RAG belongs in their app. We build these systems as part of our AI development services and generative AI work, so the advice below comes from implementation, not theory.
Key takeaways
- RAG means retrieve first, then generate. The model’s weights never change.
- It fits knowledge that changes often, must be cited, or must stay private.
- Fine-tuning changes how a model behaves; RAG supplies what it knows. Many production systems use both.
- Answer quality depends more on retrieval (chunking, search, permissions) than on which LLM you pick.
- Start narrow: one knowledge source, one use case, and a test set of real user questions.
Tell us what knowledge your assistant needs to use, and we’ll recommend where to start.
How Does RAG Work? A Step-by-Step Breakdown
RAG runs in two phases: an indexing phase that prepares your knowledge ahead of time, and a query phase that retrieves the right passages and hands them to an LLM for every question.
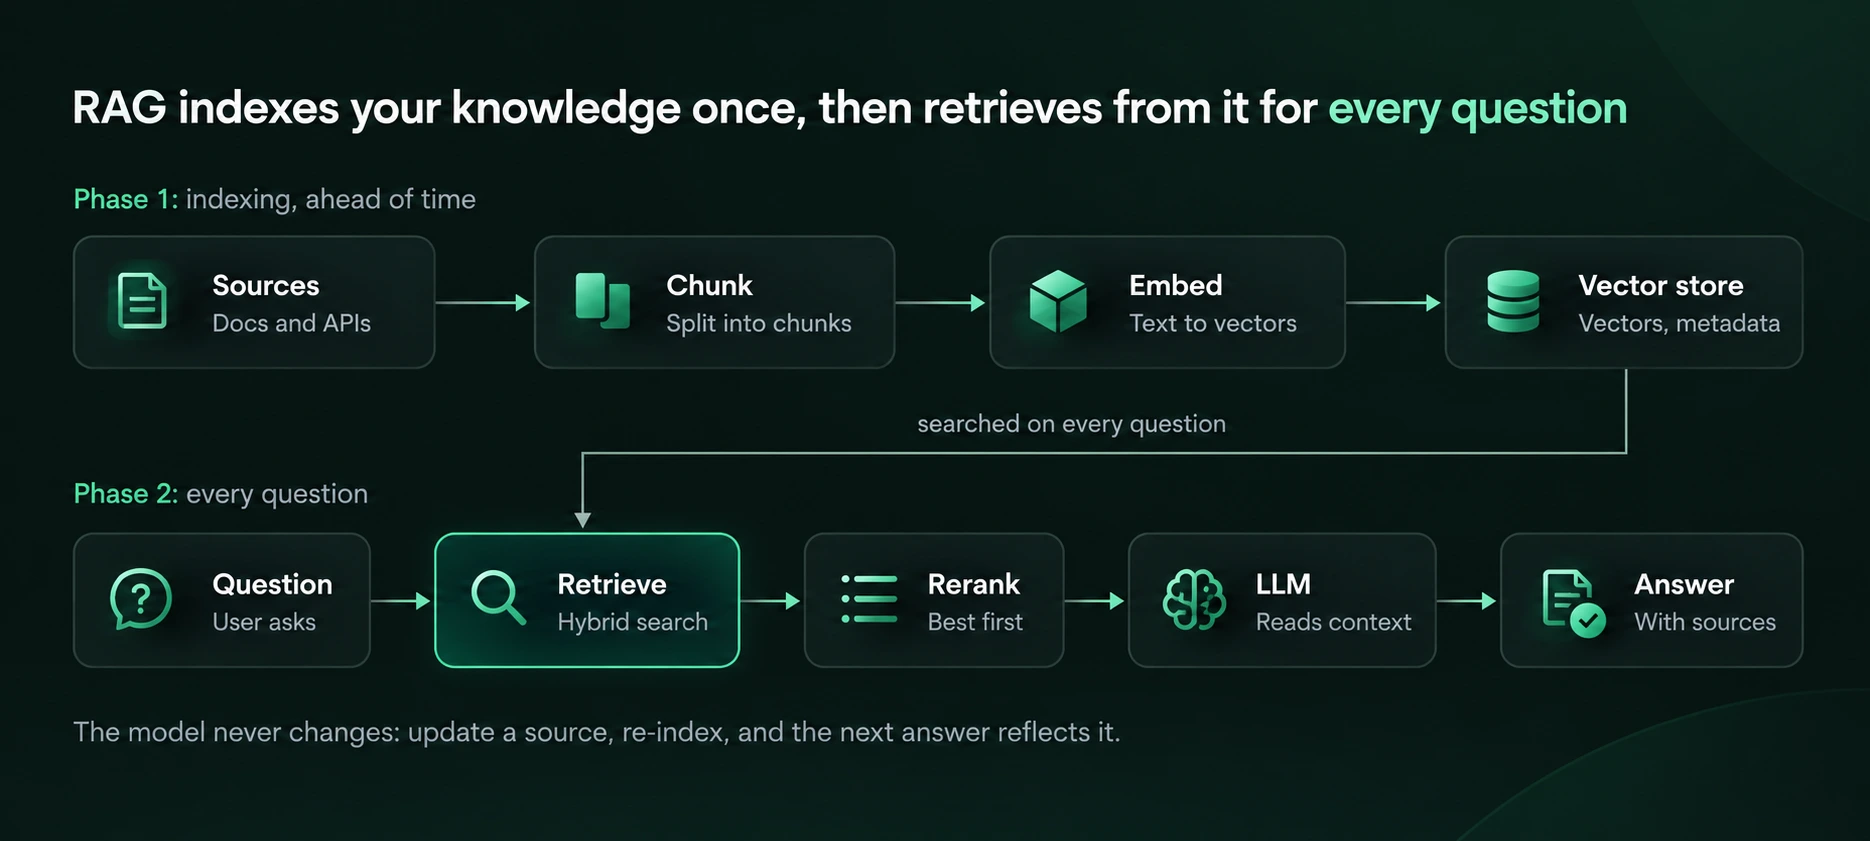
The top lane runs whenever your sources change. The bottom lane runs for every question and searches the same vector store.
Phase 1: Indexing (done before anyone asks anything)
- Collect sources. PDFs, wiki pages, help-center articles, support tickets, CRM records, database rows, or API responses.
- Chunk the content. Split documents into passages (often a few hundred words) and keep headings and metadata so each chunk still makes sense alone.
- Embed each chunk. An embedding model converts text into a vector, a list of numbers that captures meaning, so similar ideas sit close together.
- Store vectors and metadata. Save them in a vector database or search index along with the source, date, and who is allowed to see it.
Phase 2: Query (every time a user asks)
- Interpret the question. The system may rewrite it to be clearer or break it into sub-questions.
- Retrieve. Search finds the most relevant chunks using semantic, keyword, or hybrid search, filtered by the user’s permissions.
- Rerank. A second model reorders the results so the best evidence comes first.
- Augment the prompt. Instructions, the user’s question, and the top chunks are assembled into one prompt.
- Generate. The LLM writes an answer from that context and points to its sources.
Example. A clinic staffer asks a scheduling assistant, “What is our cancellation window for telehealth visits?” The retriever finds the current policy page, the LLM answers from that text, and the reply links to the policy.
If you are building the user-facing side of this, our guide on how to build an AI app like ChatGPT covers the interface and backend, and our chatbot development services page explains how we connect a chatbot to a knowledge base.
We build RAG systems that connect LLMs to your documents, databases, and APIs
Why Do Business Apps Use RAG?
Business apps use RAG because it fixes three problems that make a plain LLM risky at work: stale knowledge, no access to private data, and answers nobody can verify.
- Current answers without retraining. The model itself never changes. Update a document in the knowledge base and the very next answer reflects it.
- Private knowledge under your control. Contracts, tickets, and internal wikis stay in your own store instead of being baked into a model. Retrieval can also be filtered by user role, so a sales rep never sees HR files.
- Fewer hallucinations, with receipts. In a 2025 peer-reviewed study of cancer-information chatbots, models answering from training data alone hallucinated in roughly 40% of responses. Chatbots grounded in a curated, reliable source produced none to 6% on questions that source covered (JMIR Cancer). The study was small (62 questions), so treat it as direction, not a guarantee.
Adoption is growing but uneven. A 2026 systematic review of 63 studies found that enterprise adoption is largely still experimental, and fewer than 15% of the studies addressed the real-time integration needed for production.
For regulated industries, see our healthcare app development work and our guide to agentic AI in healthcare.
RAG vs Fine-Tuning vs Long Context vs a Plain LLM
Use RAG when the model lacks knowledge, fine-tuning when it lacks behavior, a long context window when your whole source fits in one prompt, and a plain LLM only for general tasks. The table compares the options side by side.
Approach | Best for | Knowledge freshness | Source citations | Setup effort | Main weakness |
Plain LLM (prompting only) | General writing, brainstorming, public knowledge | Frozen at training date | None | Lowest | Guesses on private or recent facts |
Long context window | One small, stable document set | As fresh as what you paste in | Possible, manual | Low | Pays for every token on every request; does not scale |
RAG | Changing, private, or large knowledge bases | Update the source and re-index | Built in | Medium | Retrieval quality and added latency |
Fine-tuning | Tone, output format, domain behavior | Frozen at training time | None | High | Does not reliably store facts or stop hallucinations |
RAG + fine-tuning | Brand voice plus current facts | Current | Built in | Highest | Most moving parts to maintain |
Fine-tuning is often mistaken for a fix for wrong answers. It shapes how a model responds, not how truthful it is, so a fine-tuned model can state wrong facts in a perfect brand voice. A practical rule of thumb, in line with Progress’s RAG vs fine-tuning guide:
- Knowledge changes weekly or faster, or you need a source trail? Start with RAG.
- Need strict JSON output, a persona, or a house style? Fine-tune.
- Need both? Fine-tune for behavior and put RAG underneath for facts.
Before either, try a stronger system prompt with examples. Many “AI problems” are prompt problems. To choose the model that sits behind your retrieval layer, read our comparison of Claude, GPT, Gemini, and Llama and our guide on how to build an AI model.
RAG Use Cases for Business Apps
The best RAG use cases share one trait: the answer lives in a document or record that someone changes regularly. These are the patterns that come up most in business apps.
Industry or function | Use case | Typical data source | Why RAG fits |
Customer support | Answer product and policy questions in chat | Help center, release notes, past tickets | Docs change often; answers need links |
Healthcare | Policy lookup, clinical guideline search, staff Q&A | Policies, protocols, approved clinical references | Citations and access control matter |
Fintech and finance | Compliance Q&A, report summaries, policy search | Policies, filings, product terms | Audit trail for every answer |
Ecommerce | Product Q&A and guided shopping | Catalog, specs, reviews, return policy | Inventory and prices change daily |
HR and people ops | Benefits and policy assistant | Handbook, benefits docs, HRIS | Role-based answers from current policy |
If your app must take action, not just answer, RAG becomes the memory layer for an AI agent. Our guide to what agentic AI is explains the difference, and our comparison of an AI chatbot, voice bot, and AI agent helps you pick the right interface.
For industry-specific detail, read our posts on AI chatbots in ecommerce, AI agents for finance, and AI agents in HR. If you want a build partner, see our AI agent development services.
See how we build chatbots grounded in your help center and CRM
Pros and Cons of RAG
RAG’s main strengths are freshness, citations, and privacy control. Its main costs are pipeline complexity, added latency, and total dependence on the quality of your data.
Pros | Cons |
Answers stay current: re-index a document instead of retraining a model | More moving parts: ingestion, chunking, search, reranking, permissions, monitoring |
Answers can cite the passage they came from | Retrieval adds latency, and retrieved context makes every prompt longer |
Private data stays in your store, with role-based filtering at retrieval | Weak or outdated sources produce weak answers |
Lower hallucination rates when sources are reliable | Can still miss the right passage and answer wrongly, or not at all |
Model-agnostic: swap the LLM without rebuilding the knowledge layer | Does not change tone, format, or style on its own |
Two findings from the JMIR Cancer study are worth knowing. First, source quality dominates. Chatbots that retrieved from Google search results hallucinated far more than those retrieving from a curated source (odds ratio 9.4), because the model trusts whatever it retrieves. Second, grounding creates a coverage trade-off. RAG chatbots answered 36% to 81% of questions, against 100% for chatbots without retrieval, because they declined when the source lacked information. Half the test questions fell outside the curated source by design, so the exact rates will differ in your app, but the pattern holds: plan for gaps.
When not to use RAG
- Your whole knowledge base is small and stable enough to fit in one prompt.
- You only need a different tone or output format, which is a prompting or fine-tuning job.
- The question needs live transactional data such as balances or inventory. Call an API or database tool instead of searching documents.
- You need calculations across every record. A database query does that better than passage retrieval.
Not sure RAG is the right fit? A short call is enough to tell you whether you need RAG, fine-tuning, or neither. Talk to Our AI Team
RAG Architecture and Tech Stack Options
A production RAG stack has five layers: ingestion, indexing, retrieval, generation, and evaluation. Most teams can start with managed or open-source components and swap them as needs grow. The stack is mostly standard technology: in the 63-study review cited earlier, 80.5% of implementations relied on standard retrieval frameworks such as FAISS or Elasticsearch.
Layer | Common options | Pick it when |
Ingestion and parsing | Custom ETL, document loaders, OCR for scans | Sources include PDFs, scans, or many systems |
Embedding model | Hosted APIs (OpenAI, Google, Cohere) or open-source models | Hosted for speed to market; open-source for data residency or cost at scale |
Vector store or search index | Postgres with pgvector, Pinecone, Weaviate, Qdrant, Elasticsearch, OpenSearch | pgvector if you already run Postgres; a dedicated store for large or high-traffic corpora |
Retrieval | Hybrid keyword plus vector search, a reranking model, metadata filters | Exact terms (SKUs, clause numbers) matter alongside meaning |
LLM | GPT, Claude, Gemini, Llama | Match to accuracy, latency, cost, and privacy needs |
Evaluation | Test sets, Ragas, TruLens, human review | Always |
Beyond basic RAG you will meet three variants: hybrid RAG (keyword plus vector search with reranking), agentic RAG (an agent decides what to retrieve and when to retry), and GraphRAG (retrieval over a graph of entities and relationships, which costs more to build).
Start with basic or hybrid RAG. Add agentic or graph retrieval only when your test questions prove the simple version cannot answer them. If you want a ChatGPT-style assistant grounded in your own data, our custom ChatGPT development service covers exactly that pattern.
How Much Does a RAG System Cost, and How Long Does It Take?
RAG cost comes from four places: building the pipeline, embedding and storing your data, running queries, and keeping quality high over time. Exact figures depend on your data and traffic, so use the drivers below to scope a quote rather than trusting a single number.
- Data preparation: scanned PDFs, messy formats, and many sources raise effort.
- Model usage: larger models and longer retrieved context raise per-query cost.
- Retrieval design: reranking, graph, or agentic retrieval add build and run cost.
- Infrastructure and compliance: dedicated vector stores, private hosting, and HIPAA or SOC 2 needs.
- Evaluation and upkeep: frequent content changes and many user roles need ongoing work.
On timeline, a narrow pilot with one source and one use case ships far sooner than a full rollout. Hardening it for production, with permissions, evaluation, monitoring, and compliance, is where most of the schedule goes.
For related budgeting, see our breakdowns of AI agent development cost and AI agent running costs.
7 Mistakes That Break RAG (and How to Evaluate Quality)
Most failed RAG projects fail at retrieval, not at the language model, so measure retrieval and generation separately.
- Indexing messy or outdated documents. The model trusts what it retrieves. Remove duplicates, expired policies, and drafts before indexing.
- Chunking blindly. Splitting a table or policy clause in half destroys its meaning. Chunk by structure, keep headings, and attach metadata.
- Using semantic search alone. Meaning-based search can miss exact identifiers such as SKUs, drug names, or clause numbers. Hybrid search with reranking usually fixes this.
- Ignoring permissions. If retrieval is not filtered by user role, the assistant can surface documents a user should never see. Enforce access at the retrieval layer, not in the prompt.
- Having no “I don’t know” path. Instruct the model to say when the context lacks the answer, and show sources.
- Skipping a test set. Without real questions and expected answers, you cannot tell whether a change helped.
- Never refreshing the index. A RAG system on stale data is a confident old chatbot. Automate re-indexing and track document age.
Use these metrics to score quality:
Metric | Question it answers | How to check |
Context relevance | Did retrieval fetch the right passages? | Compare retrieved chunks with a labeled answer source |
Faithfulness | Is every claim supported by the retrieved text? | Automated judge plus human spot checks |
Refusal behavior | Does it decline when the source lacks the answer? | Add out-of-scope questions to the test set |
Latency and cost per query | Is it fast and affordable enough to ship? | Track percentiles and tokens per request |
Score retrieval first. If the right passage never reaches the model, no prompt tweak will rescue the answer. To keep the first release small and testable, our guide to AI-powered custom MVP development shows how we scope a first version.
Build a RAG System With Zenkoders
Zenkoders designs and ships RAG systems as part of its AI development services, connecting LLMs to your business data with a focus on accuracy, data security, and cost-efficient scaling. Since 2019 we have delivered 1,000+ projects for startups and enterprises across the USA, from mobile apps to AI chatbots and agents. For healthcare clients, we build on a HIPAA-focused architecture.
Common RAG use cases we build for:
- Customer-support assistants grounded in your help center and CRM
- Internal knowledge search with role-based access
- Document Q&A for your own files, policies, and reports
- RAG-backed AI agents that retrieve, then act
Ready to scope yours? Book a free strategy call, or explore our AI development services and chatbot development services.
Conclusion
RAG is the most practical way to make an LLM useful with private, changing business knowledge. If you are weighing a build, talk to our AI team.
Share your use case and data sources. We’ll come back with an approach and an estimate, with no commitment.
FAQs:
What does RAG stand for in AI?
RAG stands for retrieval-augmented generation. It is a technique where an AI model retrieves relevant information from an external knowledge source and uses it to generate a grounded answer.
Is RAG better than fine-tuning?
Neither is better overall, because they solve different problems. RAG adds knowledge the model lacks and keeps it current, while fine-tuning changes tone, format, and behavior.
Does RAG stop AI hallucinations?
No, but it reduces them when the retrieved sources are reliable. In the 2025 JMIR Cancer study, chatbots without retrieval hallucinated in about 40% of responses, versus 0% to 6% for chatbots grounded in a curated source on covered questions. Poor retrieval or poor sources can still produce wrong answers.
Is RAG safe for sensitive data like healthcare or financial records?
It can be, but RAG alone does not make a system compliant. Safety depends on access control at retrieval, encryption, audit logs, data-handling agreements with every vendor, and, in healthcare, a HIPAA-focused architecture. See our healthcare app development page.
What is the difference between RAG and an AI agent?
RAG is a retrieval technique that grounds answers in your data. An AI agent plans and takes actions, often using RAG as one of its tools. Learn more in our guide to what agentic AI is.